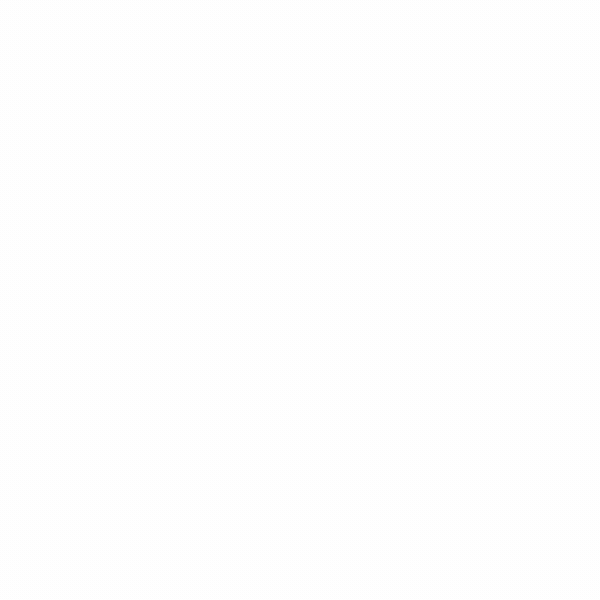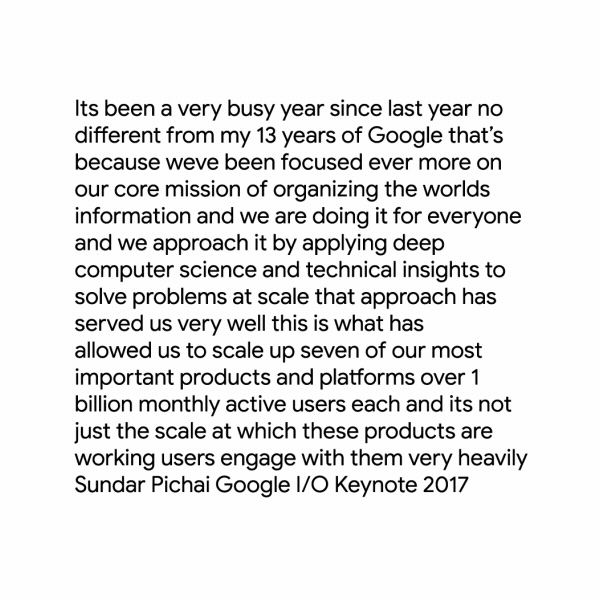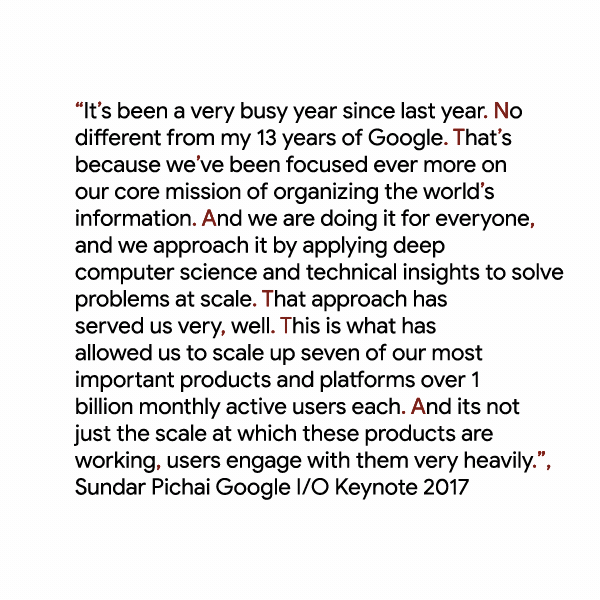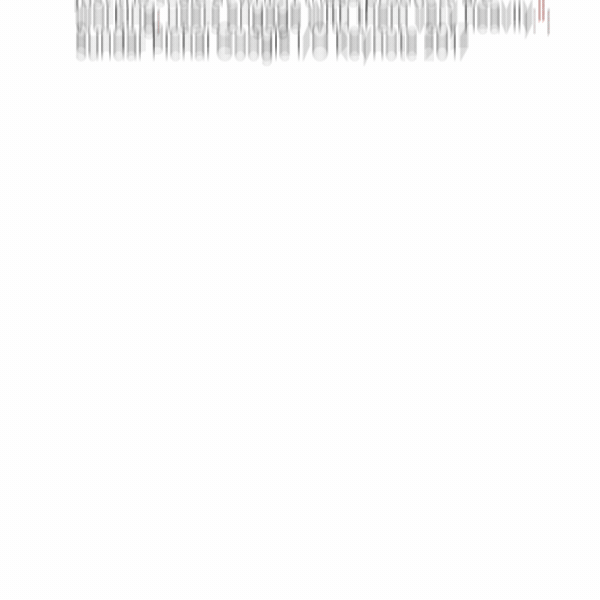10 April 2018

Conserve the Sound is an archive of noises from old tape players, projectors, and other dying tech


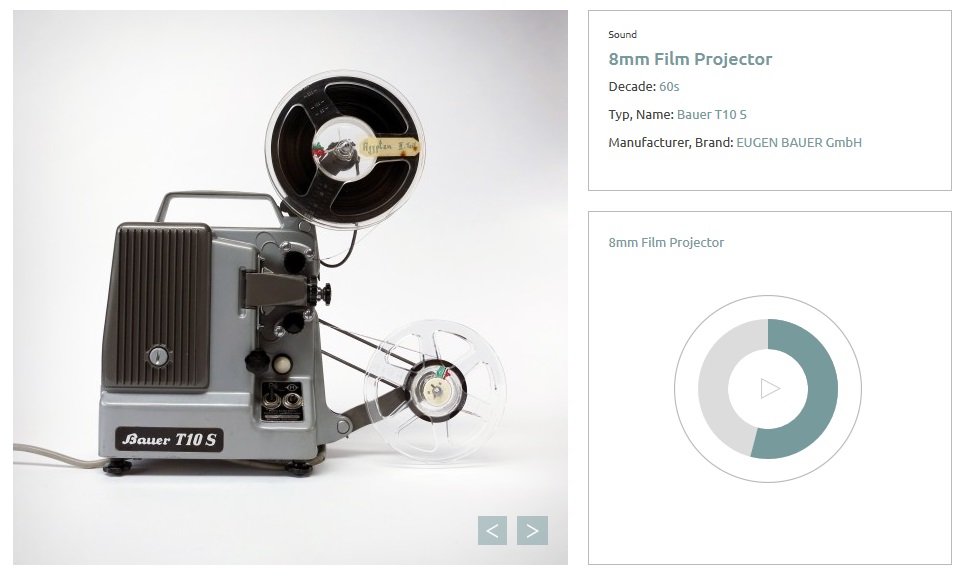
All of us grew up around tech different from what we have today, and many of us look back on those devices with fondness. But can you recall the exact sound your first Casio keyboard made, or the cadence of a rotary phone’s clicks? Conserve the Sound aims to, well, conserve the sound of gadgets like these so that future generations will know what it sounded like to put a cartridge in the NES.

It’s actually quite an old project at this point, having been funded first in 2013, but its collection has grown to a considerable size. The money came from German art institution Film & Medienstiftung NRW; the site was created (and is maintained) by creative house Chunderksen.

The whole thing is suitably minimal, much like an actual museum: you find objects either by browsing randomly or by finding a corresponding tag, and are presented with some straightforward imagery and a player loaded with the carefully captured sound of the device being operated.

Though the items themselves are banal, listening to these sounds of a bygone age is strangely addictive. They trigger memories or curiosity — was my Nintendo that squeaky? Didn’t my rotary phone click more? What kind was it anyway? I wonder if they have my old boombox… oh! A Viewmaster!

The collection has grown over the years and continues to grow; it now includes interviews with experts in various subjects on the importance of saving these sounds. You can even submit your own, if you like. “We welcome suggestions in general, sound suggestions, stories, anecdotes and of course collaborations,” write the creators.

I for one would love to revisit all the different modems and sounds I grew up using. 2400, 9600, 14.4, 28.8, all the way up to 56.6. Not exactly pleasant noises, admittedly, but I anticipate they will bring back a flood of memories, Proust-style, of BBSes, hours-long download times, and pirated screen savers.


Read Full Article

Congress should demand Zuckerberg move to “one share, one vote”


Mark Zuckerberg is an autocrat, and not hypothetically. Through his special voting rights held in FB’s Class B shares, he wields absolute command of the company, while owning just a handful of percentage points of the company’s equity.

Like any autocrat, he has taken extraordinary measures to maintain control over his realm. He produced a plan exactly two years ago that would have zeroed out the voting rights for everyday shareholders with a new voteless Class C share, only to pull back at the last minute as a Delaware court case was set to begin. He has received the irrevocable proxies of many Facebook insiders, allowing him to control their votes indefinitely. Plus, any Class B shares that are sold are converted to Class A shares, allowing him to continue to consolidate power as people leave.

And now, borrowing a page straight out of George Orwell’s 1984, he has even tried to retract and disappear his own messages to others on his platform (which has now been retracted itself after it became public).

While Congress is right to focus on Cambridge Analytica, and electoral malfeasance, and political ads, and a whole crop of other controversies surrounding Facebook, it should instead direct its attention to the single solution that would begin to solve all of this: dissolve Facebook’s dual-class share structure and thereby democratize its ownership.

Just as congressmen are elected under the principle of “one man, one vote,” it should demand that Facebook follow the highest standards used by most other publicly-listed companies and return to “one share, one vote.”

Zuckerberg himself should certainly agree with this. After all, the original logic of creating a voteless share class was that the company’s financial performance was strong and Zuckerberg needed to be protected to continue it that way. The plan was announced the same quarter that Facebook crushed its financial results, and there was an absolutely implied connection between those results and the controlling stake held by Zuckerberg.

Yet in the two months, from its intraday peak at a share price of $195.32 on February 1, 2018 to today’s price of $160, Facebook has lost more than $100 billion in its market cap. If Congressional inquiries eventually lead to further regulation, it could further erode the value of the stock. It’s easy to argue that a chief executive should be protected when the performance of a company is rocketing up. It’s much harder when everything is crumbling and no one is being held accountable.

Shareholders may have been blinded by Facebook’s dizzying growth over the past few years, but we now know that the edifice of that growth is far more tenuous than we ever knew before. Zuckerberg’s 15-year apology tour can no longer sustain the view that corporate governance should be ignored for the good of the share price.

There’s just one problem though, and it is the problem that confronts any country with a tyrant: shareholders have no power here to affect change. They can’t change the composition of the board, they can’t change the management team. They can’t change anything at all, since one person controls the realm with an iron fist. A proposal back in 2015 to move to “one share, one vote” was struck down at Facebook’s shareholder meeting.

I am not asking for Zuckerberg to be fired, or to resign. I think people should clean up their own messes, and few people have the means to clean up Facebook right now other than him. But I do think there should be consequences, and so far, there have been exactly zero. Zuckerberg has to personally relinquish his control, and no act of mea culpa would better show that he understands the consequences of his actions.

There is a counter-argument, which is that ravenous mobs of private investors would swoop into Facebook and force the company to steal even more data from users to sell to advertisers if Zuckerberg lost control. I am wholly unconvinced though, mostly because Facebook has basically done precisely that over its entire history. Plus, any further deterioration of trust with users would strike at the heart of its financial results.

Zuckerberg says in his prepared statement that, “My top priority has always been our social mission of connecting people, building community and bringing the world closer together.” There are few things he could do to build the community around Facebook’s leadership than sharing the burdens and the responsibilities with a wider, more diverse set of people. Take a page from American history, and abolish the discrimination inherent in the dual-class share vote.


Read Full Article

HQ Trivia finally gets social with ‘Friends on HQ’ update


The popular quiz startup HQ Trivia is beginning to roll out the first of many new social features to its app focused on leveraging competition with friends and family during game time.

HQ Trivia has managed to bring people together in real life to play the game on their phones, but the startup has done surprisingly little when it comes to bringing social interactions to the app itself. Today, HQ is launching a new feature called “Friends on HQ,” which will roll out to U.K. users for today’s game, with a U.S. launch to follow “soon after,” the company says.

The feature lets users search for and connect with friends and family inside the app. Once users connect, they’ll be able to keep track of how everyone is doing and which friends of theirs are playing in any given quiz match. It’s a very easy move for HQ that adds some familial familiarity to the game’s battle royale quiz format.

Building these connections will be important to strengthening its core group of players, which has grown to the millions. HQ Trivia has begun chasing sponsorship deals with companies like Warner Bros. and Nike. As the startup looks to experiment more with monetization, having a user base that is devoted enough to deal with some of these changes will be essential.

This update is far from a one-off and seems to signify a shift for the app. According to a spokesperson, “this update forms the basis of a variety of new features that HQ will be rolling out soon, leveraging friends’ connections.”


Read Full Article

09 April 2018

Facebook shut down Russian APT28 trolls before the 2016 U.S. election


The most interesting part of Mark Zuckerberg’s prepared testimony for congress that was released today shows that Facebook has been fighting Russian election interferences since before the 2016 U.S. presidential race. Facebook shut down accounts related to Russian GRU military intelligence-linked group APT28, also known as Fancy Bear, which had created an organization called DCLeaks run by fake personas to seed stolen information to journalists.

Wired detailed the methods of the “Advanced Persistent Threat 28” group in January 2017. APT28 uses zero-day exploits, malware-equipped spearfishing emails, publicly known but unfixed vulnerabilities in computer systems, and malicious iFrames embedded in hacked websites to steal people’s files. The group has been connecte to attacks on NATO, French television station TV5Monde, and the World Anti-Doping Agency.

The Washington Post reported in September 2017 that Facebook had detected the APT28 accounts in June 2016 and reported their activity to the FBI, but didn’t detail that Facebook had fought back directly by shutting down their accounts.

Here’s Zuckerberg’s full explanation of the situation:

“Elections have always been especially sensitive times for our security team, and the 2016 U.S. presidential election was no exception. Our security team has been aware of traditional Russian cyber threats — like hacking and malware — for years. Leading up to Election Day in November 2016, we detected and dealt with several threats with ties to Russia. This included activity by a group called APT28, that the U.S. government has publicly linked to Russian military intelligence services. But while our primary focus was on traditional threats, we also saw some new behavior in the summer of 2016 when APT28-related accounts, under the banner of DC Leaks, created fake personas that were used to seed stolen information to journalists. We shut these accounts down for violating our policies.”

The Post reported that APT28 were known for stealing data and military plans from political targets, leading Facebook’s security team to assume it was planning traiditional espionage rather than a more public-facing disinformation campaign to skew the election. But they did share their findings with the FBI. Later when Facebook discovered APT28 had created the the Guccifer 2.0 hacker persona and DCLeaks Facebook to deliver stolen emails and documents to journalists, Facebook contacted the FBI again.

Now Zuckerberg’s testimony indicates Facebook didn’t just hand off responsibility to the FBI, but worked to combat the trolls on its own.

This information could give Facebook and Zuckerberg a better defense as he’s questioned by the U.S. Senate Judiciary and Commerce committees Tuesday, then the U.S. House Energy and Commerce Committee on Wednesday. If Facebook can demonstrate that it wasn’t completely asleep at the wheel regarding election interference, it could get softer treatment than if Congress thinks it was caught completely off-guard.

You can see Zuckerberg’s full prepared testimony below:

Zuckerberg Statement to Congress by Jordan Crook on Scribd


Read Full Article

This is Mark Zuckerberg’s prepared statement for Congress


Ahead of Mark Zuckerberg’s testimony before Congress on Wednesday, the House Energy and Commerce Committee has released the Facebook CEO’s prepared statement.

In it, Zuckerberg explains that Facebook has always been an optimistic organization, focusing on connecting people and giving them a voice. But Zuckerberg also admits that the idealist train of thought might have blinded the company to potential misuses of Facebook’s toolset.

But it’s clear now that we didn’t do enough to prevent these tools from being used for harm as well. That goes for fake news, foreign interference in elections, and hate speech, as well as developers and data privacy. We didn’t take a broad enough view of our responsibility, and that was a big mistake. It was my mistake, and I’m sorry. I started Facebook, I run it, and I’m responsible for what happens here.

The statement also goes over both the Cambridge Analytica scandal and Russian election interference, thoroughly explaining what happened in each situation and what Facebook is doing to solve these problems.

Zuckerberg is set to testify before the Senate tomorrow and before Congress on Wednesday. We’ll be covering both hearings.

You can read the full statement embedded below.


Read Full Article

Facebook will tell you today if Cambridge Analytica had access to your data


Last week, Facebook revealed that 87 million or so users potentially had their data improperly shared with Cambridge Analytica — and you’ve no doubt been wondering if yours is among them. Today the site will share that information with users.

The disclosure arrives by way of a new “protecting your information” link set to appear at the top users’ feeds. The landing page lets users manage the third-party apps using the site to log-in and lets them know whether that information has been improperly shared with Cambridge Analytica

“We have banned the website ‘This Is Your Digital Life,’ which one of your friends used Facebook to log into,” the note is set to read. “We did this because the website may have misused some of your Facebook information by sharing it with a company called Cambridge Analytica.”

The news was announced last week, as part of a larger data privacy push for the site, which has scrambled to rehabilitate its image in the wake of political upheaval tied to information sharing. The slate of announcements also included new restrictions to Events, Groups and Pages APIs, along with Facebook log in, among others.

Earlier today, the site announced that it is working with nonprofits to improve the study of the ways in which its data is being used to impact elections.


Read Full Article

Google launches an improved speech-to-text service for developers


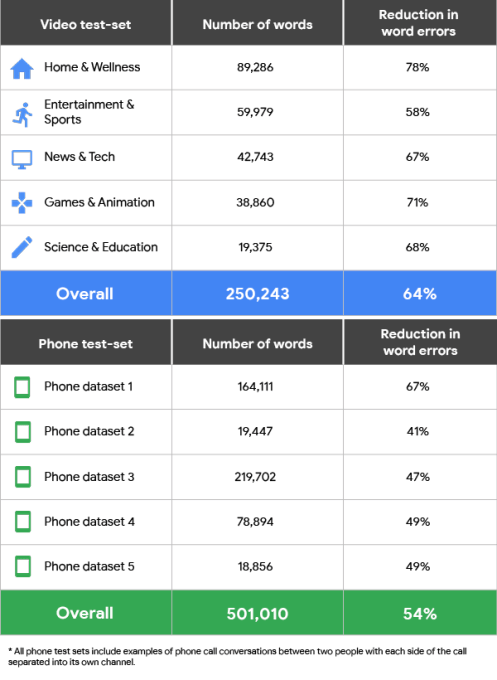
Only a few weeks after launching a major overhaul of its Cloud Text-to-Speech API, Google today also announced an update to that service’s Speech-to-Text voice recognition service. The new and improved Cloud Speech-to-Text API promises significantly improved voice recognition performance. The new API promises a reduction in word errors around 54 percent across all of Google’s tests, but in some areas the results are actually far better than that.

Part of this improvement is a major new feature in the Speech-to-Text API that now allows developers to select between different machine learning models based on this use case. The new API currently offers four of these models. There is one for short queries and voice commands, for example, as well as one for understanding audio from phone calls and another one for handling audio from videos. The fourth model is the new default, which Google recommends for all other scenarios.

In addition to these new speech recognition models, Google is also updating the service with a new punctuation model. As the Google team admits, its transcriptions have long suffered from rather unorthodox punctuation. Punctuating transcribed speech is notoriously hard though (just ask anybody who has ever tried to transcribe a speech by the current U.S. president…). Google promises that its new model results in far more readable transcriptions that feature fewer run-on sentences and more commas, periods and question marks.

With this update, Google now also lets developers tag their transcribed audio or video with some basic metadata. There is no immediate benefit to the developer here, but Google says that it will use the aggregate information from all of its users to decide on which new features to prioritize next.

Google is making a small change to how it charges for this service. Like before, audio transcripts cost $0.006 per 15 seconds. The video model will cost twice as much, though, at $0.012 per 15 seconds, though until May 31, using this new model will also cost $0.006 per 15 seconds.


Read Full Article

Facebook teams with nonprofits to launch election research commission


Facebook’s post-Cambridge Analytica apology tour continues this morning with the announcement of an initiative aimed at helping social science researchers gauge the site’s impact on key political events.

In a post issued this morning, the company’s Vice President of Communications and Public Policy Director of Research outlined the plan and hammered home its focus on impartial data collection. “Facebook will not have any right to review or approve their research findings prior to publication,” the pair writes.

The initiative is backed by a who’s who of nonprofit foundations that will sound familiar to anyone who’s spent any time with the dial tuned to NPR. The group hopes lessons learned from Brexit and the presidential election will help shed some light on how the social media behemoth could potentially impact upcoming elections like U.S. midterms, Brazil, India and Mexico — a pretty aggressive timeframe for this kind of work.

“[W]e think it’s an important new model for partnerships between industry and academia,” the pair writes. “Second, the last two years have taught us that the same Facebook tools that help politicians connect with their constituents — and different communities debate the issues they care about — can also be misused to manipulate and deceive.” 

If you've followed me for a while, you know one of my top priorities for 2018 in making sure Facebook prevents…

Posted by Mark Zuckerberg on Monday, April 9, 2018

Mark Zuckerberg addressed the creation of the commission in a post today that once again acknowledged that Facebook’s response time could have been better. The site has gotten pushback from nearly all sides on its handling of the issue, including a recent dressing down from the U.S. Senate.

“Looking back, it’s clear we were too slow identifying election interference in 2016, and we need to do better in future elections,” the CEO writes. “This is a new model of collaboration between researchers and companies, and it’s part of our commitment to protect the integrity of elections around the world.”

No word yet on the timeframe for all of this, but Zuckerberg promised an update “soon.”


Read Full Article

App downloads and revenue again broke records in the first quarter of 2018


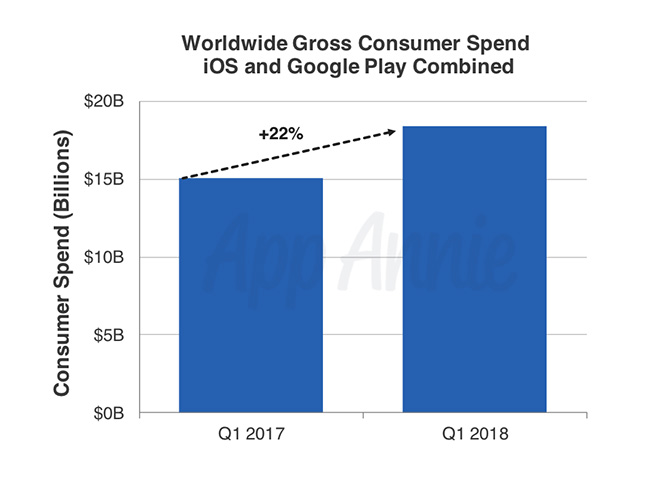
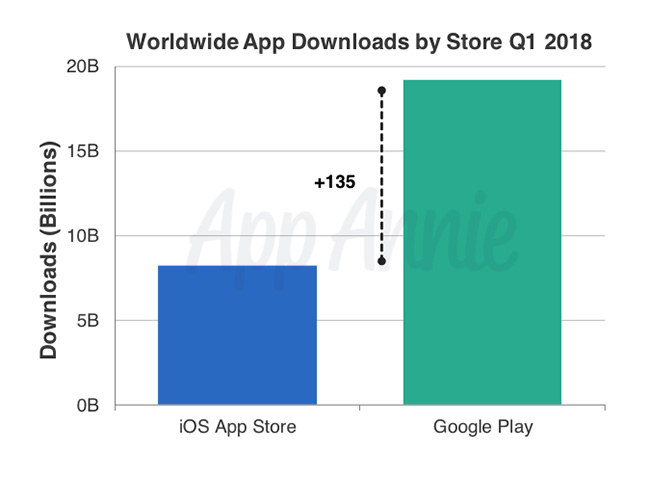
Global app downloads and consumer spending in apps had yet another record quarter, according to a new report from App Annie, out on Monday. In the first quarter of 2018, iOS and Google Play downloads grew more than 10 percent year-over-year to reach 27.5 billion – the highest figure to date. In addition, consumer spending on iOS and Google Play grew 22 percent year-over-year to reach $18.4 billion – also a record number.

The download figure is especially notable because App Annie is not counting app updates or re-installs. That means someone re-downloading an app on a new phone – like one received as a gift over the holidays – wouldn’t have been counted here. Only new app installs were counted.

Plus, the report points out that the total dollar amount to the app economy is much higher than the $18.4 billion reported for Q1, as App Annie only takes into account paid apps, in-app purchases, and subscriptions. It’s not measuring things like in-app advertising, the commerce taking place in apps (e.g. shopping and ride-sharing), or the money being made on the third-party Android app stores around the world.

This is not the first time App Annie has reported record numbers for downloads and consumer spending. The app marketplaces have continued to see steady growth, even as reports of app saturation in the U.S. circulate.

In Q4 2017 – the busy holiday quarter – the app stores had also broken these same records around downloads and revenues. Specifically, Google Play saw its highest downloads to date in the fourth quarter. The app stores had a record-breaking Q3 2017, too – something App Annie attributed then to the growth of the app market in China, India, and other Southeast Asian nations.

This time, App Annie pointed to India, Indonesia and Brazil’s impact on the year-over-year growth in Google Play downloads, and the U.S., Russia and Turkey’s impact on the growth of iOS downloads.

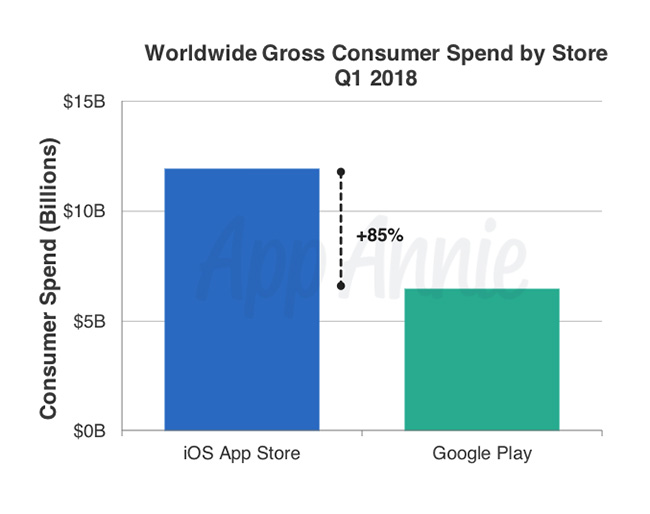
Also notable is that Google Play achieved another record of its own in Q1 2018, with record growth in consumer spend thanks to the U.S, followed by Japan and the Philippines. The Play Store grew 25 percent year-over-year, versus iOS’s 20 percent growth. Despite this, iOS continued to have a large lead in terms of total dollars spent.

Music & Audio along with Entertainment apps had a big impact on Google Play spending, the report noted, both on a quarter-over-quarter and year-over-year basis. This is attributed to the rise in music and video subscription services delivered via apps. App Annie isn’t the only one to spot this trend – app store intelligence firm Sensor Tower had previously found that top subscription video on demand apps grew by 77 percent in 2017, reaching $781 million in revenues across iOS and Google Play. And Netflix became 2017’s top non-game app by revenue.

App Annie said also that iOS spending in Q1 2018 benefitted from subscriptions to health and fitness apps, driven by New Year’s Resolutions and people’s embrace of the subscription model. The U.S., followed by the U.K. then Germany saw the largest market share growth quarter-over-quarter and year-over-year.

Combined, Google Play and the iOS App Store offered 6.2 million apps by the end of Q1 2018, with games driving downloads across both stores during the quarter. PUBG Mobile and Fortnite were especially big, App Annie noted.

Shopping apps also saw large year-over-year growth in market share, the report found.

More broadly, the new report is yet another example of how big a role emerging markets are having on app downloads and the app economy. This trend, while still remarkable, is not all that new. In 2016, China overtook the U.S. in App Store revenue, and App Annie has continued to note China, India and other emerging markets as key drivers of growth in its quarterly and annual reports.


Read Full Article

Bots on Twitter share two-thirds of links to popular websites: Pew


It’s official: Bots are doing a lot of PR grunt work on Twitter — especially when it comes to promoting porn websites.

That perhaps unsurprising conclusion about what automated Twitter accounts are link sharing comes courtesy of a new study by the Pew Research Center which set out to quantify one aspect of bot-based activity in the Twittersphere.

Specifically the researchers wanted to know what proportion of tweeted links to popular websites are posted by automated accounts, rather than by human users?

The answer they came up with is that around two-thirds of tweeted links to popular websites are posted by bots rather than humans.

The researchers say they were interested in trying to understand a bit more about how information spreads on Twitter. Though for this study they didn’t try to delve directly into more tricky (and sticky) questions about bots — like whether the information being spread by these robots is actually disinformation.

Pew’s researchers also didn’t try to determine whether the automated link PR activity actually led to significant levels of human engagement with the content in question. (Something that can be difficult for external researchers to determine because Twitter does not provide full access to how it shapes the visibility of tweets on its platform, nor data on how individual users are making use of controls and settings that can influence what they see or don’t on its platform).

So, safe to say, many bot-related questions remain to be robustly investigated.

But here at least is another tidbit of intel about what automated accounts are up to vis-a-vis major media websites — although, as always, these results are qualified as ‘suspected bots’ as a consequence of how difficult it is to definitively identify whether an online entity is human or not. (Pew used Indiana University’s Botometer machine learning tool for identifying suspected bots; relying on a score of 0.43 or higher to declare likely automation — based on a series of their own validation exercises.)

Pew’s top-line conclusion is that suspected automated accounts played a prominent role in tweeting out links to content across the Twitter ecosystem — with an estimated 66% of all tweeted links to the most popular websites likely posted by automated accounts, rather than human users.

The researchers determined website popularity by first conducting an analysis of 1.2 million English-language tweets containing links (pulling random sample tweet data via Twitter’s streaming API) — which they boiled down to a list of 2,315 popular sites, i.e. once duplicates and dead links were weeded out.

They then categorized these into content domains, with any links that pointed to any other content on Twitter (i.e. rather than externally) collected into a single Twitter.com category.

After that they were able to compare how (suspected) bots vs (probable) humans were sharing different categories of content.

Below are the results for content being PRed by suspected bots — as noted above it’s unsurprisingly dominated by adult content. Though bots were found to be responsive for the majority of link shares to popular websites across the category board. Ergo, robots are already doing a major amount of PR grunt work…
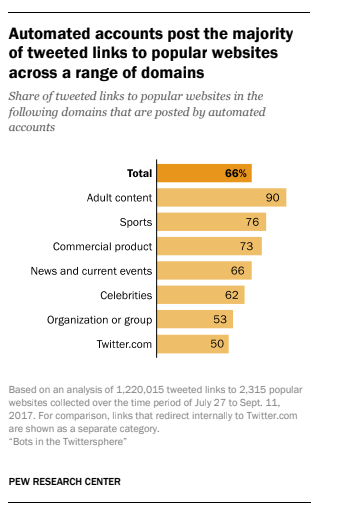
 

(Looking at that, a good general rule of thumb seems to be that if a Twitter account is sharing links to porn sites it’s probably not human. Or, well, it’s a human’s account that’s been hacked.)

The researchers also found that a relatively small number of automated accounts were responsible for a substantial share of the links to popular media outlets on Twitter. “The 500 most-active suspected bot accounts alone were responsible for 22% of all the links to these news and current events sites over the period in which this study was conducted. By contrast, the 500 most-active human accounts were responsible for just 6% of all links to such sites,” they write.

Clearly bots aren’t held back by human PR weaknesses — like needing to stop working to eat or sleep.

Pew says its analysis also suggests that certain types of news and current events sites appear “especially likely” to be tweeted by automated accounts. “Among the most prominent of these are aggregation sites, or sites that primarily compile content from other places around the web. An estimated 89% of links to these aggregation sites over the study period were posted by bot accounts,” they write.

tl;dr: Bots appear to be less interested in promo-ing original reporting. Or, to put it another way, bot grunt work is often being deployed to try to milk cheap views out of other people’s content.

Another interesting observation: “Automated accounts also provide a somewhat higher-than-average proportion of links to sites lacking a public contact page or email address for contacting the editor or other staff.

“The vast majority (90%) of the popular news and current events sites examined in this study had a public-facing, non-Twitter contact page. The small minority of sites lacking this type of contact page were shared by suspected bots at greater rates than those with contact pages. Some 75% of links to such sites were shared by suspected bot accounts during the period under study, compared with 60% for sites with a contact page.”

Without reading too much into that finding, it’s possible to theorize that sites without any public content page or email might be more likely to be hosting disinformation. (Pew’s researchers don’t go as far as to join those dots exactly — but they do note: “This type of contact information can be used to submit reader feedback that may serve as the basis of corrections or additional reporting.”)

That said, Pew also found political content to be of relatively lower interest to bots vs other types of news and current affairs content — at least judging by this snapshot of English-language tweets (taken last summer).

“[C]ertain types of news and current events sites receive a lower-than-average share of their Twitter links from automated accounts,” the researchers write. “Most notably, this analysis indicates that popular news and current events sites featuring political content have the lowest level of link traffic from bot accounts among the types of news and current events content the Center analyzed, holding other factors constant. Of all links to popular media sources prominently featuring politics or political content over the time period of the study, 57% are estimated to have originated from bot accounts.”

The researchers also looked at political affiliation — to try to determine whether suspected bots skew left or right in terms of the content they’re sharing.

(To determine the ideological leaning of the content being linked to on Twitter Pew says they used a statistical technique known as correspondence analysis — examining the media link sharing behavior of publications’ Twitter audience in order to score the content itself on an idealogical spectrum ranging from “very liberal” to “most conservative”.)

In fact they found automated accounts posting a greater share of content from sites that have “ideologically mixed or centrist human audiences”. At least where popular news and current events sites “with an orientation toward political news and issues” are concerned.

“The Center’s analysis finds that suspected autonomous accounts post a higher proportion of links to sites that are primarily shared by human users who score near the center of the ideological spectrum, rather than those shared more often by either a more liberal or a more conservative audience,” they write. “Automated accounts share roughly 57% to 66% of the links to political sites that are shared by an ideologically mixed or centrist human audience, according to the analysis.”

Pew adds that right-left differences in the proportion of bot traffic were “not substantial”.

Although, on this, it’s worth emphasizing that this portion of the analysis is based on a pretty small sub-set of an already exclusively English-language and US-focused snapshot of the Twittersphere. So reading too much into this portion of the analysis seems unwise.

Pew notes: “This analysis is based on a subgroup of popular news and current events outlets that feature political stories in their headlines or have a politics section, and that serve a primarily U.S. audience. A total of 358 websites out of our full sample of 2,315 popular sites met these criteria.”

Really the study underlines a core truth about Twitter bots: They’re often used for spam/PR purposes — to try to drive traffic to other websites. The substance of what they’re promoting varies, though it can clearly often be adult content.

Bots are also often used to try to cheaply drive clicks to a cheap content aggregator site so that external entities can cheaply cash in thanks to boosted ad views and revenue.

Political disinformation campaigns may well result in a lower volume of bot-generated spam/PR than porn or content farms. Though the potential damage — to democratic processes and societal institutions — is arguably way more serious. As well as being very difficult to quantify.

And where the influence of bots is concerned, we still have many more questions than answers.


Read Full Article
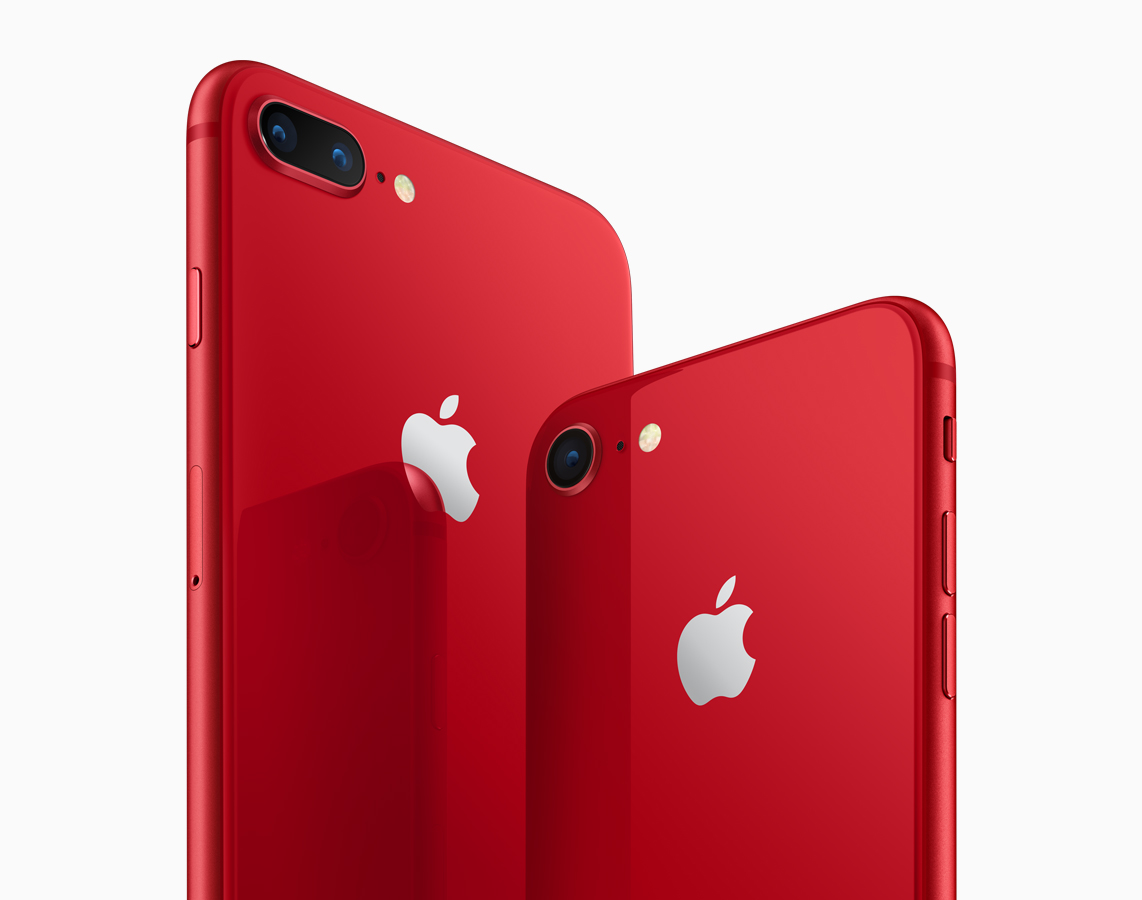
Apple releases a red iPhone 8


Apple is doing it again. The company just unveiled a new version of the iPhone 8 and iPhone 8 Plus. It has a bright red enclosure and a black front. A portion of Apple’s proceeds will fund HIV/AIDS grants from the Global Fund.

Other than that, it’s an iPhone 8. You’ll get the exact same features and components as the ones in other iPhone 8 models. The iPhone 8 is also available in gold, silver and (“space”) gray. Alas, there’s still no rose gold option.

When Apple unveiled the red version of the iPhone 7, many people didn’t understand why Apple put white bezels at the front of the device. Red and black seem like a good match. That’s why some people even bought screen protectors with black borders to fix this.

This year, Apple is switching to black. It’s interesting to see that Apple waits around 6 months before launching red versions of its iPhones. It could be a way to foster sales in the middle of a product cycle.

The red iPhone 8 is going to start at $699 with 64GB just like regular iPhone 8 models. There will be 256GB versions too. Pre-orders start tomorrow and you’ll be able to buy it in Apple stores on Friday.

For iPhone X users, Apple is launching a dark red leather folio. Apple is also sharing some numbers about its partnership with (PRODUCT)RED. Since 2006, Apple has donated $160 million to the Global Fund through limited edition iPods, iPhones and accessories.


Read Full Article

SNL roasts Mark Zuckerberg on Weekend Update


The role of Mark Zuckerberg went to Alex Moffat this weekend on Saturday Night Live’s Weekend Update.

While some bits were harmless and hilarious — “Poke! Poke! Remember that feature?” asked Moffat as he poked Jost in the shoulder. “Poke! It was flirting for cowards.” — the Facebook CEO probably didn’t laugh much on Saturday night.

Alex Moffat, playing Zuckerberg, shrieked with laughter, struggled with eye contact, and rebuked any notion that users’ should have control over their own data on Facebook.

When asked if users would be able to delete their own data, the Zuck character simply replied: “Psh, no! Because it’s mine. You gave it to me. No backsies.”

This all comes amidst the Cambridge Analytica scandal, wherein third-party apps scraped data of more than 50 million users on behalf of consultancy firm Cambridge Analytica. This has left Facebook trying to recover trust with the public, all while having lost more than $80 billion in market value since the scandal broke.

This also comes a few short days before Zuckerberg appears in Washington D.C. for both a Senate hearing on April 10 and a House Energy and Commerce hearing on April 11.

You can watch the full SNL segment below:


Read Full Article

’90s kids rejoice! Microsoft releases the original Windows 3.0 File Manager source code


Microsoft has released the source code for the original, 1990s-era File Manager that is so familiar to all of us who were dragging and dropping on Windows 3.0. The code, which is available on Github under the MIT OSS license, will compile under Windows 10.

File Manager uses the multiple-document interface or MDI to display multiple folders inside one window. This interface style, which changed drastically with later versions of Windows, was the standard for almost a decade of Windows releases.

These little gifts to the open source community are definitely fun but not everyone is happy. One Hacker News reader noted that “Most of the MSFT open source stuff is either trash or completely unmaintained. Only a couple of high profile projects are maintained and they jam opt-out telemetry in if you like it or not (despite hundreds of comments requesting them to go away). Even Scott Hanselman getting involved in one of our tickets got it nowhere. Same strong arming and disregard for customers.”

Ultimately these “gifts” to users are definitely a lot of fun and a great example of nostalgia-ware. Let me know how yours compiles by Tweeting me at @johnbiggs. I’d love to see it running again.


Read Full Article

James Murray from the Impractical Jokers talks about the future of VR


James Murray is a funny man. A producer, actor, and writer, Murray is best known as Murr on the show Impractical Jokers. I spoke to him for a Technotopia interview about the future of TV, VR, and media and he has a lot to say.

His dream? To offer immersive experiences to his audiences using VR, a dream that he thinks is still far off. Until the VR experience is out-of-the-box easy, he said, there isn’t much hope for the medium. He’s a funny guy and this is one of my favorite interviews.

Technotopia is a podcast by John Biggs about a better future. You can subscribe in Stitcher, RSS, or iTunes and listen the MP3 here.


Read Full Article

Facebook urged to make GDPR its “baseline standard” globally


Facebook is facing calls from consumer groups to make the European Union’s incoming GDPR data protection framework the “baseline standard for all Facebook services”.

The update to the bloc’s data protection framework is intended to strengthen consumers’ control over how their personal data is used by bolstering transparency and consent requirements, and beefing up penalties for data breaches and privacy violations.

In an open letter addressed to founder Mark Zuckerberg, a coalition of US and EU consumer and privacy rights groups urges the company to “confirm your company’s commitment to global compliance with the GDPR and provide specific details on how the company plans to implement these changes in your testimony before the US Congress this week”.

The letter is written by the Trans Atlantic Consumer Dialogue, and co-signed by Jeffrey Chester, the executive director of the Center for Digital Democracy in the US and Finn Lützow-Holm Myrstad, the head of the digital services section at the Norwegian Consumer Council.

“The GDPR helps ensure that companies such as yours operate in an accountable and transparent manner, subject to the rule of law and the democratic process,” they write. “The GDPR provides a solid foundation for data protection, establishing clear responsibilities for companies that collect personal data and clear rights for users whose data is gathered. These are protections that all users should be entitled to no matter where they are located.

“We favor the continued growth of the digital economy and we strongly support innovation. The unregulated collection and use of personal data threatens this future. Data breaches, identity theft, cyber-attack, and financial fraud are all on the rise. The vast collection of personal data has also diminished competition. And the targeting of internet users, based on detailed and secret profiling with opaque algorithms, threatens not only consumer privacy but also democratic institutions.”

Zuckerberg caused confusion about Facebook’s intentions towards GDPR last week when he refused to confirm whether the company would apply the same compliance measures for users in North America — suggesting domestic and Canadian Facebookers, whose data is processed in the US, rather than Ireland (where its international HQ is based), would be subject to lower privacy standards than all other users (whose data is processed within the EU) after May 25 when GDPR comes into force.

In a subsequent conference call with reporters, Zuckerberg further fogged the issue by saying Facebook intends to “make all the same controls available everywhere, not just in Europe” — yet he went on to caveat that by adding: “Is it going to be exactly the same format? Probably not. We’ll need to figure out what makes sense in different markets with different laws in different places.”

Privacy experts were quick to point out that “controls and settings” are just one component of the data protection regulation. If Facebook is truly going to apply GDPR universally it will need to give every Facebook user the same high privacy and data protection standards that GDPR mandates for EU citizens — such as by providing users with the right to view, amend and delete personal data it holds on them; and the right to obtain a copy of this personal data in a portable format.

Facebook does currently provide some user data on request — but this is by no means comprehensive. For example it only provides an eight-week snapshot of information to users about which advertisers have told it they have a user’s consent to process their information.

In denying a more fulsome fulfillment of what’s known in Europe as a ‘subject access request’, the company told one requester, Paul-Olivier Dehaye, the co-founder of PersonalData.IO, that it would involve “disproportionate effort” to fulfill his request — invoking an exception in Irish law in order to circumvent current EU privacy laws.

“[Facebook] are really arguing ‘we are too big to comply with data protection law’,” Dehaye told a UK parliamentary committee last month, discussing how difficult it has been to get the company to divulge information it holds about him. “The costs would be too high for us. Which is mindboggling that they wouldn’t see the direction they’re going there. Do they really want to make that argument?”

Whether that situation changes once GDPR is in force remains to be seen.

The new framework at least introduces a regime of much larger penalties for privacy violations — beefing up enforcement with maximum fines of up to 4% of a company’s global annual turnover. So the legal risks of trying to circumvent EU data protection law will inflate substantially in just over a month.

And Facebook has already made some changes ahead of GDPR coming into force (and likely to try to comply with the new standard) — announcing it’s shutting down a partnership with major offline and online data brokers, for example.

“Consumer groups and privacy groups, human rights groups, civil rights groups will all probably be watching how GDPR is implemented,” Finn Lützow-Holm Myrstad tells TechCrunch. “And will be ready to probably go to court to establish that these are fundamental rights for European citizens at the moment. So we’re definitely going to pay attention.

“But obviously we really want the industry to work with us and to take this seriously because if they don’t there will be a very negative spiral of court cases and a chilling effect for consumers because they will be afraid of using these services. And they will be caught in the middle because of the lack of options that they have when it comes to these services. And I don’t think that’s good for anyone. So we really hope that this is sign of change — real change — from Facebook.”

The company remains under huge pressure following revelations about how much Facebook user information was passed to a controversial political consultancy, Cambridge Analytica, by a developer using its platform to deploy a quiz app as a vehicle for harvesting personal data without most users’ knowledge or consent.

Facebook has said as many as 87M users could have had their data passed to Cambridge Analytica as a result of them or their friends downloading the app in 2014.

Zuckerberg is due to give testimony on this and likely wider issues related to privacy and data protection on his platform to US politicians this week.

One line of questioning might well focus on why Facebook has so studiously ignored years of warnings that it was not adequately locking down access to user data on its platform.

The Norwegian Consumer Council actually filed a complaint about Facebook app permissions all the way back in 2010, writing presciently then: “Third-party applications should only be given access to the information they need in order to function. Facebook should not be able to renounce responsibility for the way in which third parties collect, store or use personal data. As a facilitator and operator Facebook must take direct responsibility for the applications available on the platform.”

Myrstad says Facebook’s response to these sort of privacy complaints has been “sadly very, very little”.

On the contrary, he says the company has made it “really, really difficult to opt out of their tracking, their profiling”. He also describes Facebook’s default settings as “a nightmare” for people to understand. In terms of GDPR compliance, he says he believes Facebook will need to make changes to their business model and alter default settings — at very least for users whose data gets processed via Facebook Ireland.

“They will definitely need to have much better consent mechanisms than they do today. Much less take it or leave it,” says Myrstad. “I think there will be a discussion also in Europe, and I think it’s not yet written in stone yet how this will turn out, but we definitely also think that the amount of tracking that Facebook does by default on other websites will need an actual explicit consent — which there is not today. It’s not possible to opt out of the tracking.

“You can opt out of behavioral advertising but that’s not the same as opting out from tracking. And I think the way they do that today is not in line with GDPR… I think they will actually struggle [to comply]. They’re already struggling under current law in Europe. So they will need to make some fundamental changes to their business model.”

At the time of writing Facebook had not responded to a request for comment.


Read Full Article

08 April 2018

Dictionary app Reverso learns new tricks


Dictionary app Reverso is getting new features with its 8.0 update. There are new exercices and games to help you learn new words. Reverso also now has an integrated thesaurus.

Reverso is one of the biggest dictionary players out there. It now has over 40 million unique visitors on its website and app every month. It’s a weird industry because a significant part of the traffic on those reference websites comes from search engines. And Google Translate is quite dominant as well.

So how do you go beyond search engine optimization? Reverso has been building many different services to become your go-to destination when it comes to your language needs. For instance, you can translate a word or a sentence and find contextual examples. You can access verb conjugation, translate big chunks of text, access traditional dictionaries and more.

More interestingly, the company has been focused on language learning for its mobile app. Every time you search for something, you can add a word to your phrasebook. After that, you can then go through your phrasebook with a quiz to learn those words.

Your data will get synced across multiple devices as long as you’re logged in. You could install Reverso’s Chrome extension to add words to the mobile app for instance.

If you don’t have time to add words yourself, the company is also putting together lists of not-so-simple-but-generally-useful words. The idea is that you could be learning new words when you’re waiting in line instead of wasting time scrolling through feeds.

In addition to those new exercices, Reverso now has an integrated thesaurus. You can search for a word and tap the tiny “S” in the corner to access related words. The company has been crunching all its translations to put this together. Chances are that two words that have the same translation in multiple languages probably mean the same thing.

Reverso isn’t necessarily reinventing the wheel with all those services. But there’s an advantage in having the same company run all of those services. You can jump from one service to another, add words from multiple scenarios and more.


Read Full Article

Robo Wunderkind wants to build the Lego Mindstorms for everyone


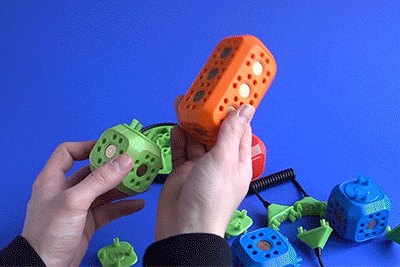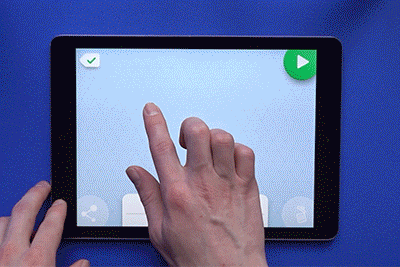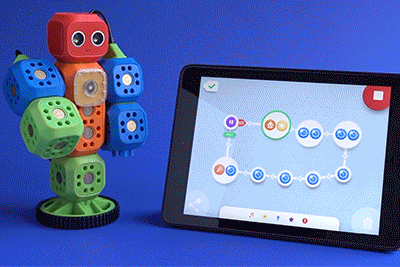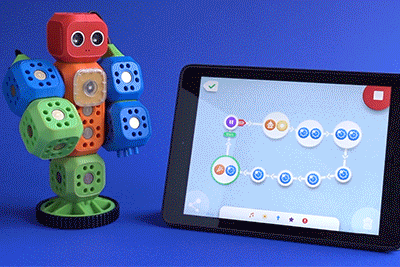
Lego Mindstorms have paved the way for many programmable toys. And Austrian startup Robo Wunderkind is building a new kind of Lego-like programmable kit. The startup first launched on the TechCrunch Disrupt stage and just raised $1.2 million (€1 million) from SOSV, Austrian Federal Promotional Bank and multiple business angels.

Compared to many programmable toys out there, Robo Wunderkind is still a Lego-like building kit. This is key as too many toys forget that it’s fun to build something with a few bricks.

Robo Wunderkind also has special blocks to turn your dumb robot into a connected one. In addition to the usual sensors, such as proximity sensors, motion detectors and light sensors, the company also has some more sophisticated ones. You can put a tiny camera in your construction, use an IR blaster and receiver and program a tiny LED screen.

But the best part is that Robo Wunderkind also sells Lego adapters so that you can put together a sophisticated robot that uses both Lego bricks and Robo Wunderkind modules.

[gallery ids="1618497,1618499,1618500,1618501,1618502,1618503,1618504,1618505,1618506"]

The company has two different apps in the store. The first one called Robo Live lets you control your robot in real time. The other one Robo Code has a brand new user interface and now detects the blocks you’re currently using.

Robo Code is where Robo Wunderkind shines because you can put together simple algorithms by arranging virtual blocks in the iPad app. It’s a good way to introduce a kid to conditional statements and loops.

You won’t build a robot as sophisticated as a robot built using Lego Mindstorms. But Robo Wunderkind seems more accessible and good way to try robotics before switching to Arduino and Raspberry Pi when your kid grows up.

The company successfully raised a little less than $250,000 on Kickstarter back in 2015. You can now buy a starter kit for $250. Advanced and professional kits will also be available soon.


Read Full Article

RSS is undead


RSS died. Whether you blame Feedburner, or Google Reader, or Digg Reader last month, or any number of other product failures over the years, the humble protocol has managed to keep on trudging along despite all evidence that it is dead, dead, dead.

Now, with Facebook’s scandal over Cambridge Analytica, there is a whole new wave of commentators calling for RSS to be resuscitated. Brian Barrett at Wired said a week ago that “… anyone weary of black-box algorithms controlling what you see online at least has a respite, one that’s been there all along but has often gone ignored. Tired of Twitter? Facebook fatigued? It’s time to head back to RSS.”

Let’s be clear: RSS isn’t coming back alive so much as it is officially entering its undead phase.

Don’t get me wrong, I love RSS. At its core, it is a beautiful manifestation of some of the most visionary principles of the internet, namely transparency and openness. The protocol really is simple and human-readable. It feels like how the internet was originally designed with static, full-text articles in HTML. Perhaps most importantly, it is decentralized, with no power structure trying to stuff other content in front of your face.

It’s wonderfully idealistic, but the reality of RSS is that it lacks the features required by nearly every actor in the modern content ecosystem, and I would strongly suspect that its return is not forthcoming.

Now, it is important before diving in here to separate out RSS the protocol from RSS readers, the software that interprets that protocol. While some of the challenges facing this technology are reader-centric and therefore fixable with better product design, many of these challenges are ultimately problems with the underlying protocol itself.

Let’s start with users. I, as a journalist, love having hundreds of RSS feeds organized in chronological order allowing me to see every single news story published in my areas of interest. This use case though is a minuscule fraction of all users, who aren’t paid to report on the news comprehensively. Instead, users want personalization and prioritization — they want a feed or stream that shows them the most important content first, since they are busy and lack the time to digest enormous sums of content.

To get a flavor of this, try subscribing to the published headlines RSS feed of a major newspaper like the Washington Post, which publishes roughly 1,200 stories a day. Seriously, try it. It’s an exhausting experience wading through articles from the style and food sections just to run into the latest update on troop movements in the Middle East.

Some sites try to get around this by offering an almost array of RSS feeds built around keywords. Yet, stories are almost always assigned more than one keyword, and keyword selection can vary tremendously in quality across sites. Now, I see duplicate stories and still manage to miss other stories I wanted to see.

Ultimately, all of media is prioritization — every site, every newspaper, every broadcast has editors involved in determining what is the hierarchy of information to be presented to users. Somehow, RSS (at least in its current incarnation) never understood that. This is both a failure of the readers themselves, but also of the protocol, which never forced publishers to provide signals on what was most and least important.

Another enormous challenge is discovery and curation. How exactly do you find good RSS feeds? Once you have found them, how do you group and prune them over time to maximize signal? Curation is one of the biggest on-boarding challenges of social networks like Twitter and Reddit, which has prevented both from reaching the stratospheric numbers of Facebook. The cold start problem with RSS is perhaps its greatest failing today, although could potentially be solved by better RSS reader software without protocol changes.

RSS’ true failings though are on the publisher side, with the most obvious issue being analytics. RSS doesn’t allow publishers to track user behavior. It’s nearly impossible to get a sense of how many RSS subscribers there are, due to the way that RSS readers cache feeds. No one knows how much time someone reads an article, or whether they opened an article at all. In this way, RSS shares a similar product design problem with podcasting, in that user behavior is essentially a black box.

For some users, that lack of analytics is a privacy boon. The reality though is that the modern internet content economy is built around advertising, and while I push for subscriptions all the time, such an economy still looks very distant. Analytics increases revenues from advertising, and that means it is critical for companies to have those trackers in place if they want a chance to make it in the competitive media environment.

RSS also offers very few opportunities for branding content effectively. Given that the brand equity for media today is so important, losing your logo, colors, and fonts on an article is an effective way to kill enterprise value. This issue isn’t unique to RSS — it has affected Google’s AMP project as well as Facebook Instant Articles. Brands want users to know that the brand wrote something, and they aren’t going to use technologies that strip out what they consider to be a business critical part of their user experience.

These are just some of the product issues with RSS, and together they ensure that the protocol will never reach the ubiquity required to supplant centralized tech corporations. So, what are we to do then if we want a path away from Facebook’s hegemony?

I think the solution is a set of improvements. RSS as a protocol needs to be expanded so that it can offer more data around prioritization as well as other signals critical to making the technology more effective at the reader layer. This isn’t just about updating the protocol, but also about updating all of the content management systems that publish an RSS feed to take advantage of those features.

That leads to the most significant challenge — solving RSS as business model. There needs to be some sort of a commerce layer around feeds, so that there is an incentive to improve and optimize the RSS experience. I would gladly pay money for an Amazon Prime-like subscription where I can get unlimited text-only feeds from a bunch of a major news sources at a reasonable price. It would also allow me to get my privacy back to boot.

Next, RSS readers need to get a lot smarter about marketing and on-boarding. They need to actively guide users to find where the best content is, and help them curate their feeds with algorithms (with some settings so that users like me can turn it off). These apps could be written in such a way that the feeds are built using local machine learning models, to maximize privacy.

Do I think such a solution will become ubiquitous? No, I don’t, and certainly not in the decentralized way that many would hope for. I don’t think users actually, truly care about privacy (Facebook has been stealing it for years — has that stopped its growth at all?) and they certainly aren’t news junkies either. But with the right business model in place, there could be enough users to make such a renewed approach to streams viable for companies, and that is ultimately the critical ingredient you need to have for a fresh news economy to surface and for RSS to come back to life.


Read Full Article

Snapchat brings back chronological Stories feed for some


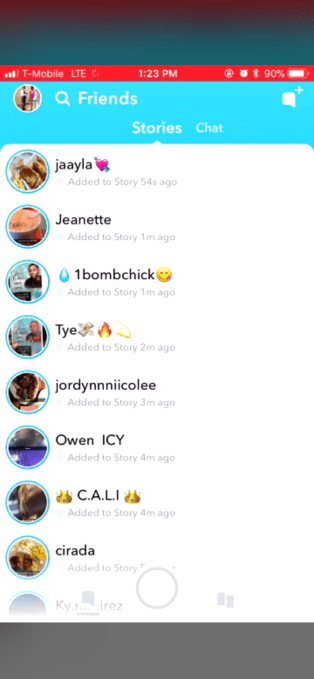
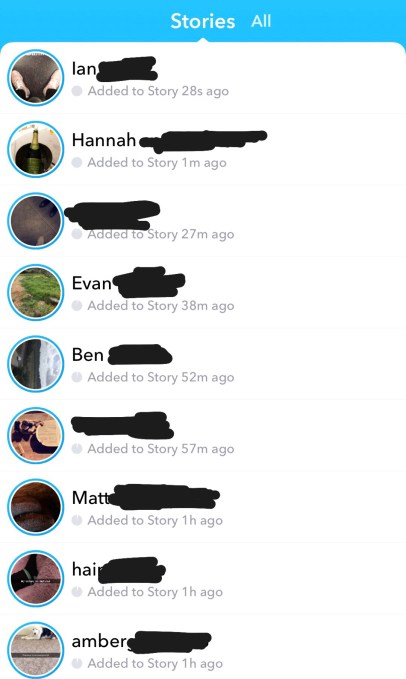
Snapchat has undone its controversial redesign’s most significant change in an update to some users today. A tab that shows Stories in reverse chronological order, replacing the redesign’s algorithmically sorted feed for many people.

We’ve reached out to Snap Inc and haven’t heard back.

Showing the most recent Stories first makes them predictable and coherent to browse. It helps you see what’s going on with friends right now. That could be helpful if you wanted to find out which friends were free to hang out or if there’s a party you could join.

Users are seeing the reverse chronological Stories feed in both the design where there’s just Stories and All tabs, as well as the design where there’s separate Stories and Chat tabs.

Snapchat has now re-added a chronological Stories feed

But reverse chronological order heavily prioritizes people who post frequently, which can bury your best friends. Snapchat’s move towards algorithmic ranking in its big redesign ensured that people you watched Stories from or chatted with most showed up at the top so you’d be less likely to miss their content. That’s similar to how Facebook’s feed worked for a long time, and how Instagram started ranking its feed two years ago. By moving social media stars and brands that don’t follow you back over to the Discover section as part of the redesign, there’s less noise in the chronological Stories list, so it works better than it did a year ago.

Switching to algorithmic sorting has helped Instagram and Twitter boost growth, which is likely why Snapchat made it part of the redesign. The company had seen daily active user growth sag from 17 percent to under 3 per quarter after the launch of Facebook’s Snapchat clone Instagram Stories. Snapchat saw growth improve after starting to roll out the algorithm-powered redesign in Q4 2017.

For the most hardcore Snapchat users who check it constantly, today’s update has been met with joy and gratitude. They were likely to see their closest friends’ posts no matter when or how infrequently they posted.

But ditching the algorithm could make it tougher for newer and less consistent Snapchat users who want to pop in and see the most relevant content instead of having to sort through distant acquaintances. That could inhibit growth. Essentially, Snapchat might have to decide between preferencing it’s most engaged and loyal users, or aiming to add more casual users.


Read Full Article